Learning by Archiving Projects
A post-mortem on frctls, anna, and synthia, and what old repos reveal when you treat archiving as a learning practice.
What three retired systems-thinking projects taught me about AI agents, publishing loops, and the difference between scaffolding and learning.
I build small systems to think with. Some turn into products, some into infrastructure, and some into a pile of mistakes with a README attached (the useful kind, it turns out).
This month I'm archiving three of them: frctls, anna and synthia. All three circled the same territory: systems thinking, organisational learning, autonomous research and AI-assisted publishing. Each tried to turn a learning loop into software, and each failed in a slightly different way.
The temptation with old repos is to call them dead and move on, but that throws away the useful part. A repo is a fossil record of decisions: what seemed important, what got overbuilt, what never got used, where the energy went.
So before archiving them, I wrote the post-mortems.
frctls: the scaffolding ate the product
frctls started as Fractals of Change, a product and content experiment about small, managed changes inside large organisations. The user was clear enough: enterprise directors trying to shift culture and productivity without the theatre of a transformation programme.
The framing was the best part. It had a mission document, explicit non-goals and a sensible first phase: thought leadership before tooling. It shipped a real Astro blog with posts on cultural tokens, change patterns, compliance, remote work and transformation. That was worth doing. If you can't explain the market, the user and the pain in writing, a UI won't save you.
It also caught me in one of my recurring traps. The scaffolding became more interesting than the thing it was scaffolding.
The repo picked up .pip, Nx fragments, agent roles, activity logs, branch rules, security scans, autonomous roadmap agents, PR monitoring and a lot of CI repair. Some of it was useful. Together it became its own gravitational field. By the end, the commit history wasn't about organisational change at all. It was about pausing automations, fixing GitHub Actions, closing generated PRs and stopping the machine from making more work.
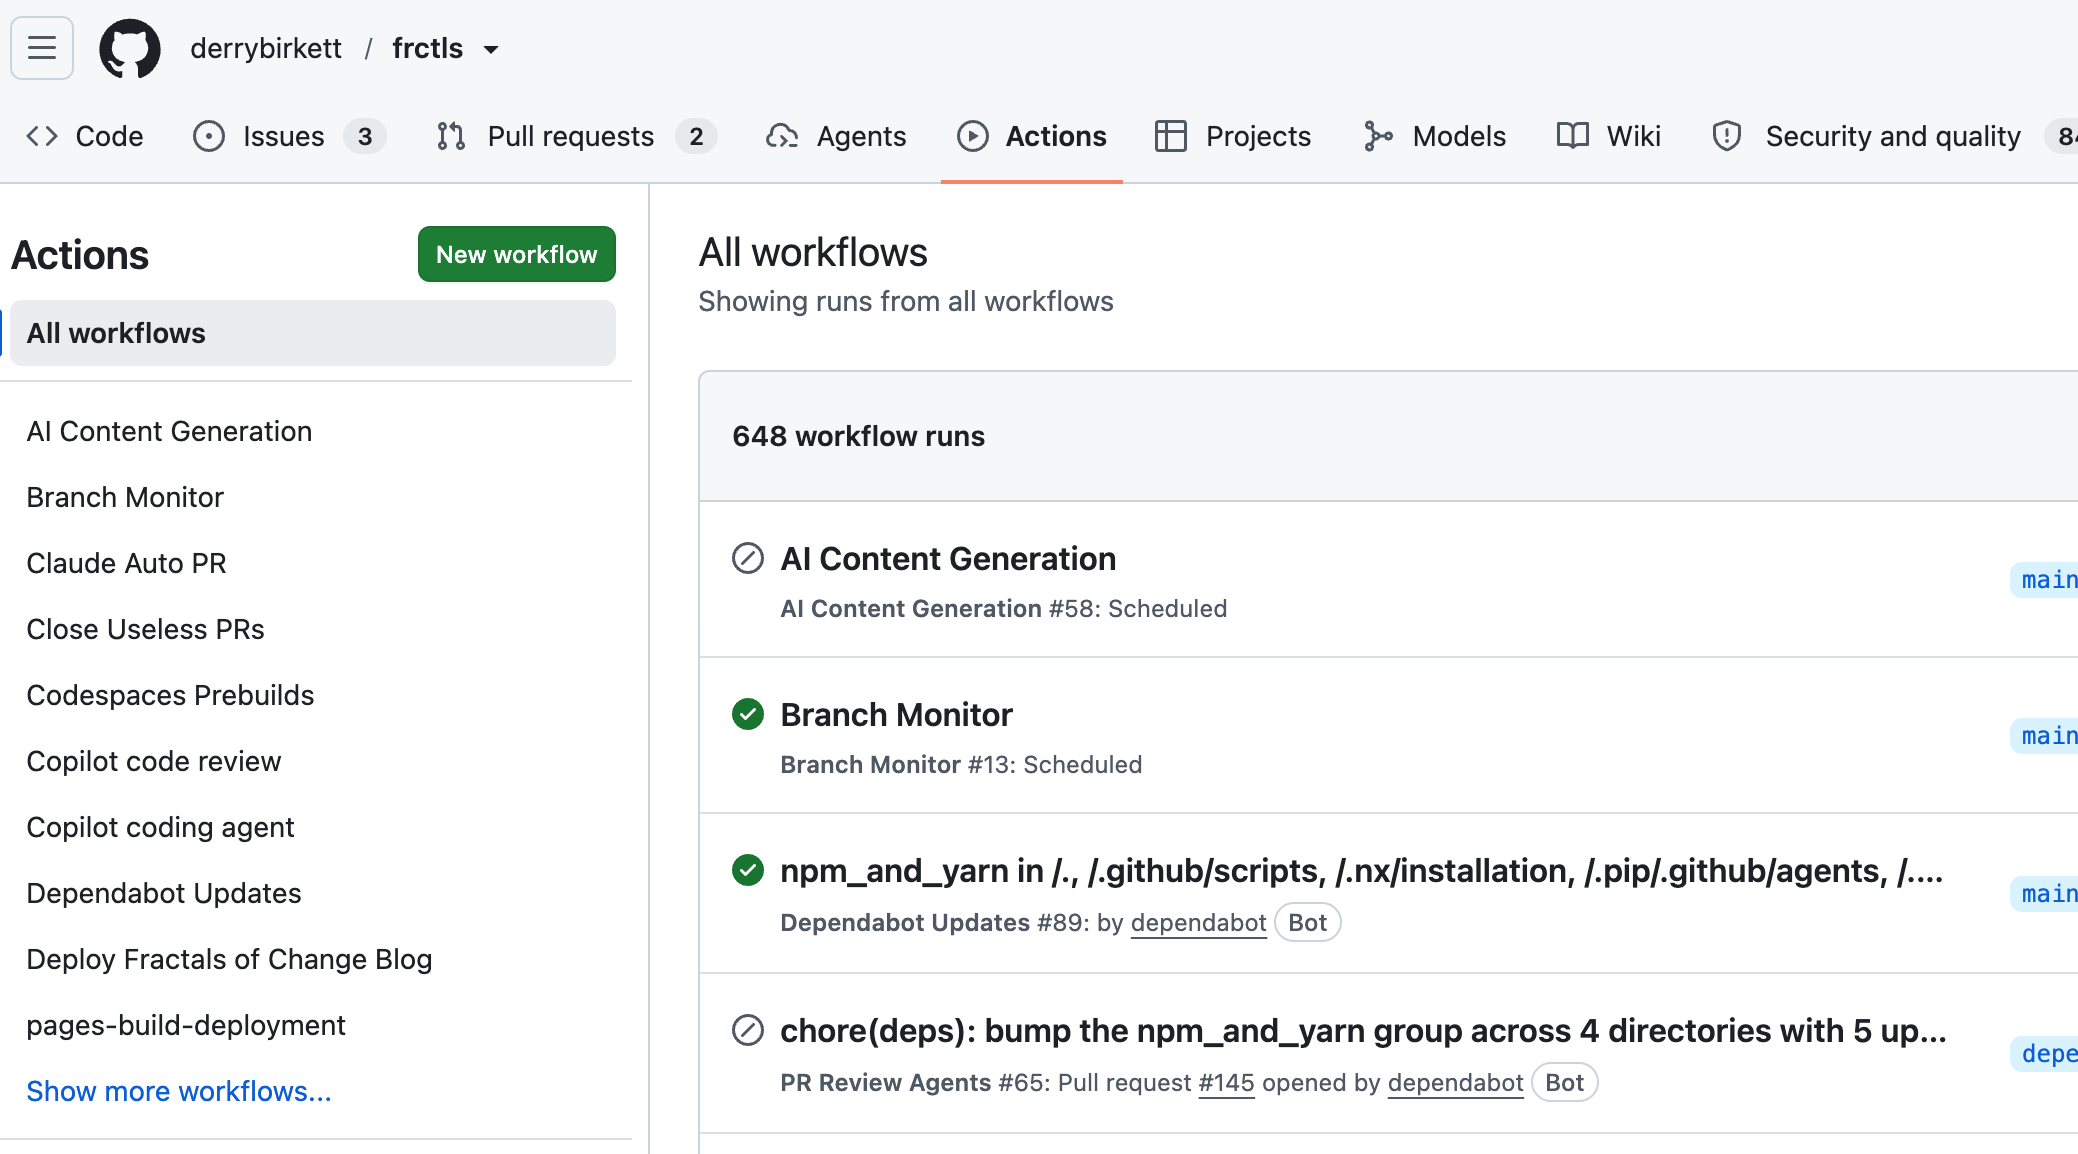
The lesson isn't "don't build systems". It's that a system only earns its keep while it keeps pressure on the product loop. Once it starts a second loop that needs its own maintenance, it's infrastructure for its own sake.
Agent governance, activity logs and repeatable scaffolding do matter. But they should only become tools once they have more than one user. Before that, they can hide the fact that there's no product.
anna: small only lasts if you defend it
anna had a sharper shape. The brief was deliberately tight: a systems-thinking blog that publishes every Thursday. One topic list, one state file, one cron route, one workflow (research, synthesise, write the article, produce workshop material). Files, no database, no agent framework, under 500 lines.
That was a good brief because it named the real job. Not "build an autonomous content platform", just publish one useful article a week. A small Next.js app, Vercel Cron, markdown output, a topic queue and a sequential workflow: all the right instincts.
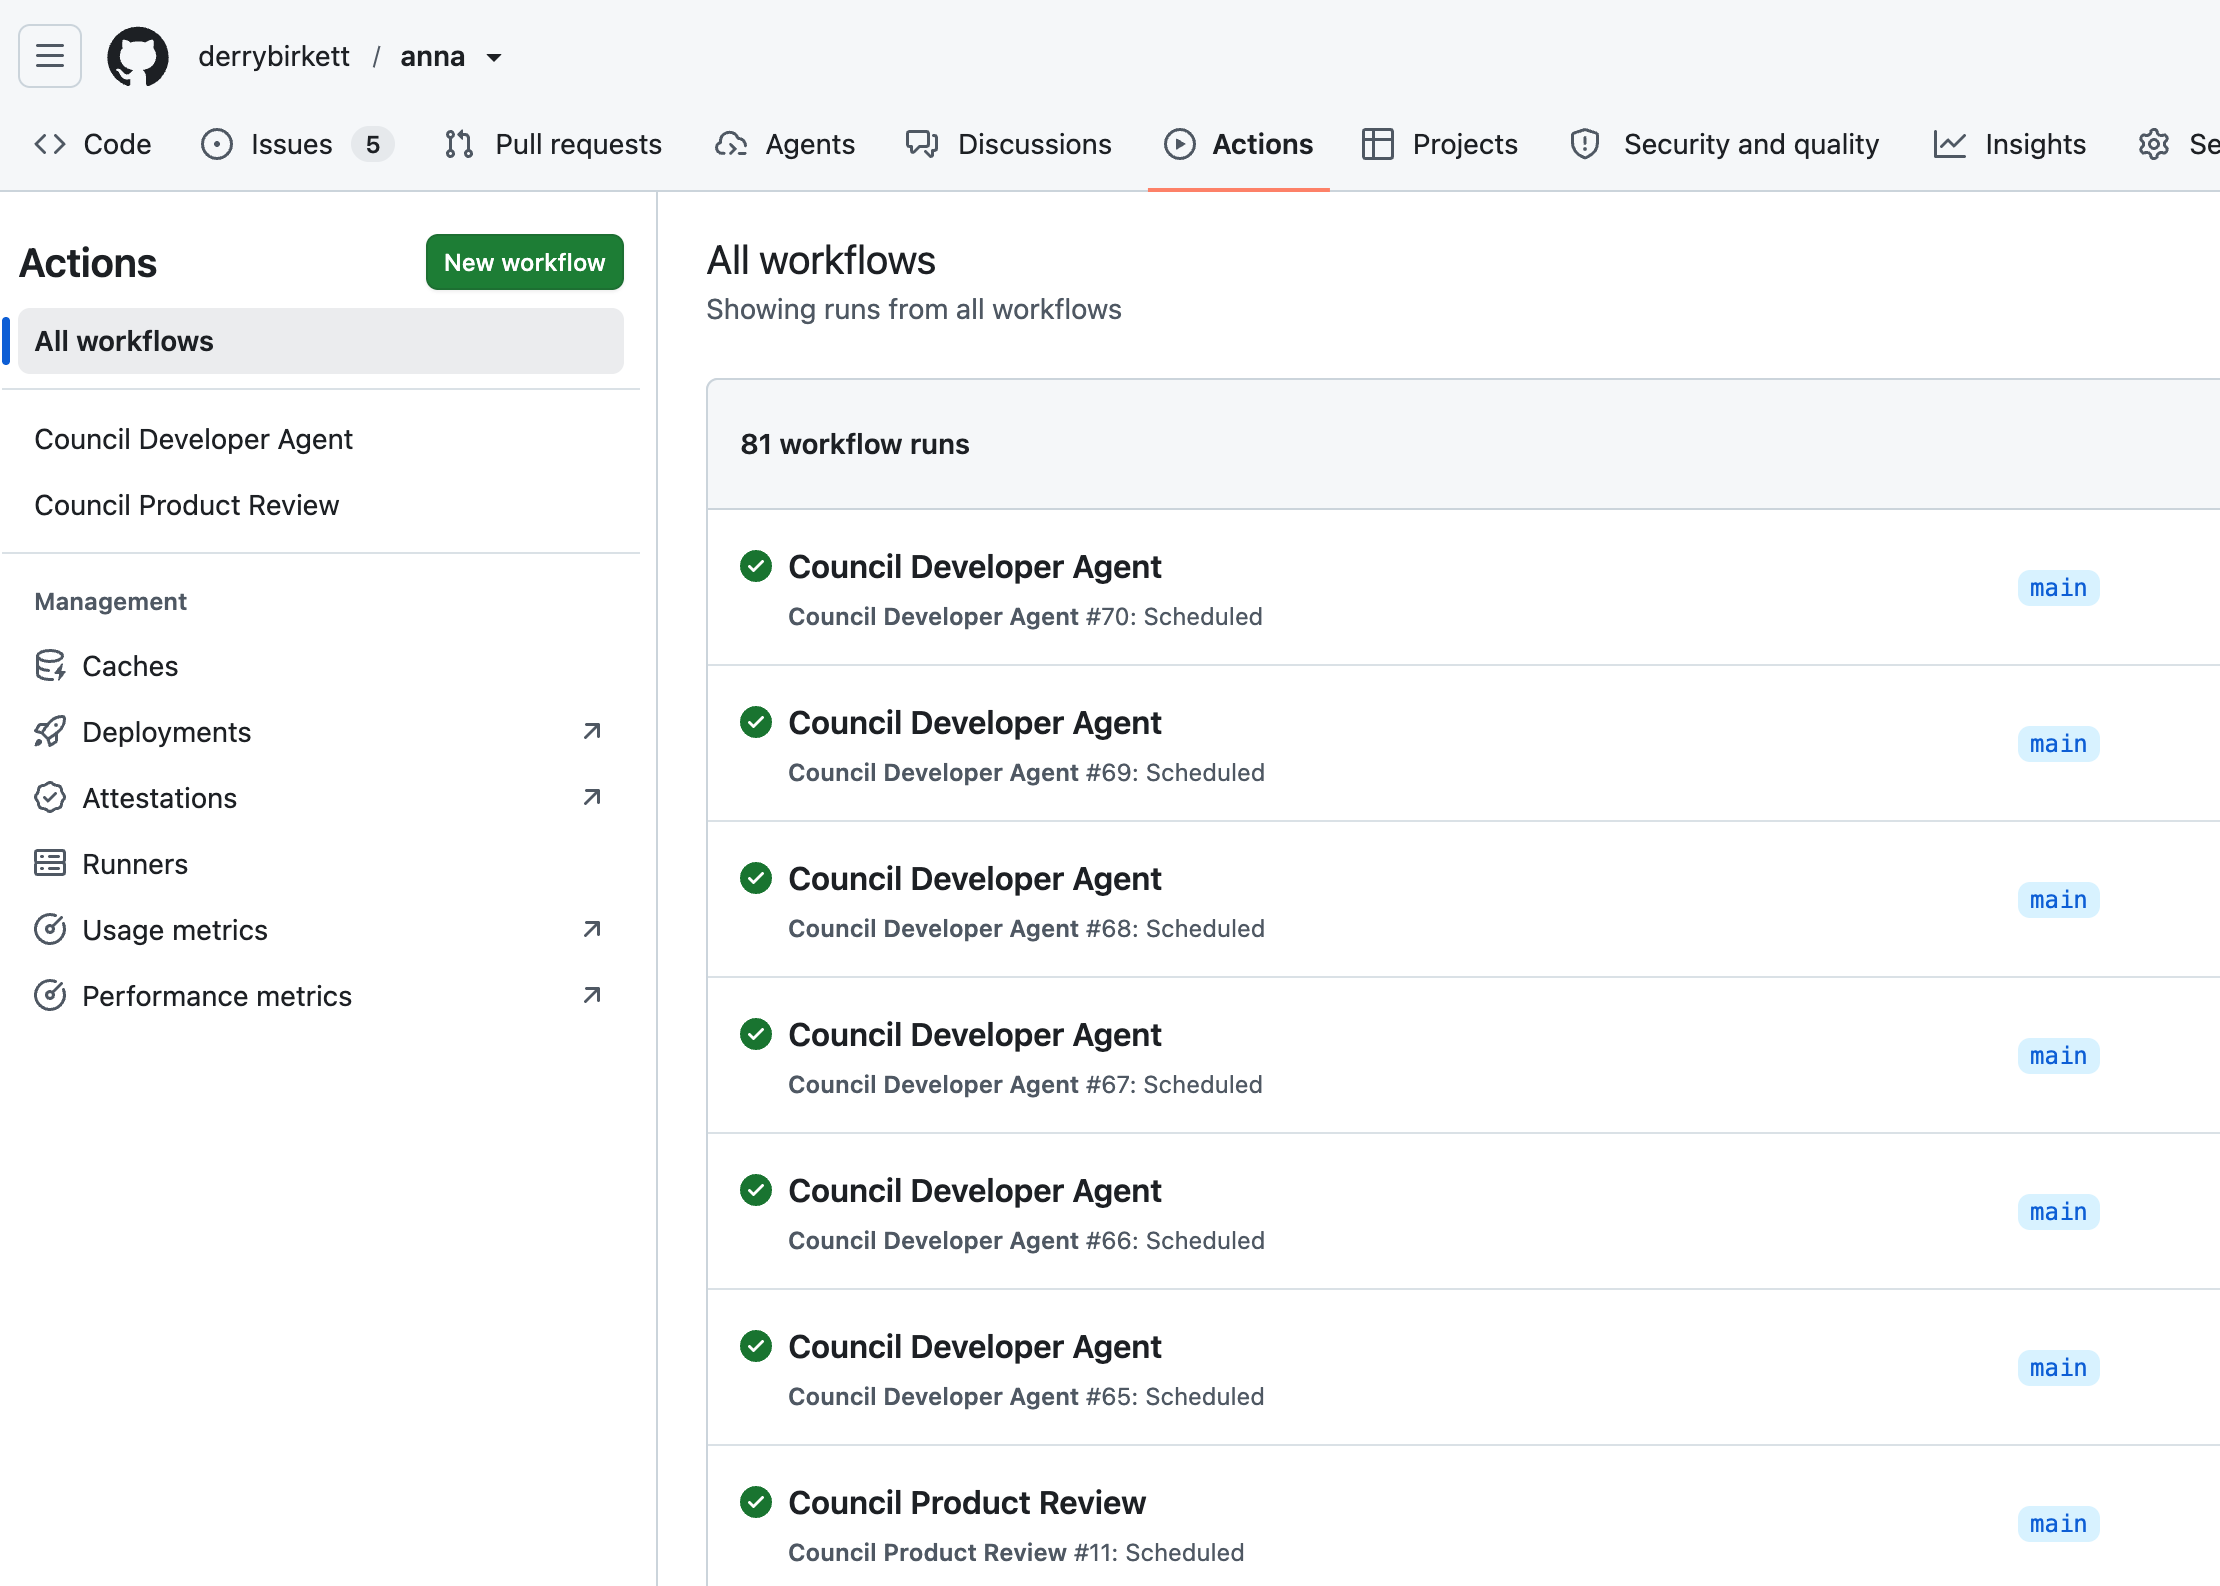
Then it started collecting exactly the machinery it was designed to avoid: provider switches, Blob storage, Council, Builder and Developer agents, submodules, CI fixes, runtime changes and shared skill infrastructure.
Some of that was fair. Production has opinions. Vercel storage behaves differently from local files, scheduled jobs need observability, and generated content has to persist somewhere. But the original constraint collapsed, and the project stopped being a publishing loop and became another agent experiment.
The clearest evidence: the repo had a content/published directory with no durable archive in it. The system for publishing existed. The publishing didn't.
Minimalism isn't achieved by starting small. It's achieved by saying no to almost everything after you start. If I rebuilt anna, I'd keep one rule above the rest: the weekly article is the product, and every task either helps the next one ship or waits.
synthia: a clean pipeline to nowhere
synthia was the cleanest build of the three: a Python package with a straight pipeline.
Scheduler -> Topic Selection -> Research -> Reflection -> Writing -> Publishing
Each step had one job. Config came from YAML and environment variables, state tracked explored topics, topic selection avoided repeats, research gathered sources, reflection used Claude to find patterns, writing produced long-form drafts and publishing wrote markdown. It was portable and testable, needed no database or queue, and had a CLI that could run once or on a schedule. As architecture, it was the most coherent of the three.
It also showed me a different limit: a pipeline isn't a learning loop until its output meets the world. synthia could write markdown files, but it had no publishing surface, no audience, no editorial review and no feedback. It could generate writing. It couldn't tell whether the writing mattered.
That's easy to miss with AI, because generation feels like progress. The model returns 2,000 words and the terminal says success. But writing isn't finished when the text exists. It's finished when it changes a reader, a decision or the author's own understanding.
Without that, the system mostly proves that automation can move tokens from one place to another.
The mistake all three shared
All three were attempts to automate learning. That's still a good ambition, but the post-mortems make the mistake obvious: I treated learning as something a system could generate, when a system can only set up the conditions for it.
Learning needs friction: a real reader or user, a real deadline, a real failure, and a change in behaviour afterwards. Automation can help with research, drafting, checking, publishing and recall. It can't remove the need for contact with reality. The best automation makes that contact cheaper and more frequent.
The failure mode is a convincing simulation of progress. A workflow runs, a PR opens, a markdown file appears, a dashboard updates. Everything is busy, and nobody has checked whether anyone read it, used it, or decided anything differently because of it.
What I'd keep
I won't revive any of them, but I'd keep one pattern from each. From frctls, mission documents, activity logs and explicit non-goals: they're the reason this post-mortem was possible at all. From anna, the constraint of one schedule, one output and one publishing loop (the brief was good, the drift was the problem). From synthia, the simple linear pipeline, wrapped in a proper editorial and distribution layer.
Put together, the system would be smaller than any of the three:
- Pick one theme.
- Keep one topic queue.
- Draft with AI.
- Review by hand.
- Publish to one place.
- Measure one signal.
- Write down what changed.
That's enough system. Anything more has to earn its place.
Archiving is research
Archiving usually gets treated as housekeeping. I think it's closer to research. It forces one question: what did this project teach me, and is that lesson still alive somewhere? If it is, the repo can close.
frctls lives on in my suspicion of overbuilt scaffolding, anna in my insistence that automation protects the product loop rather than replacing it, and synthia in my preference for small, linear agents I can inspect.
None of those repos has to stay active for the learning to.